A free AI writing detector flagged the troubleshooting guide I wrote for our internal wiki as AI-written, then changed its verdict after I fixed a typo. That’s not exactly reassuring when I’m trying to check a draft before sending it to my editor.
For this kind of check, do you actually use a paste-in website or a browser extension, and why do you trust that option? I’m only looking at free options, but I don’t want to keep rewriting my own sentences to satisfy a score. Has yours been consistent enough to be useful, or do small edits send it swinging too?
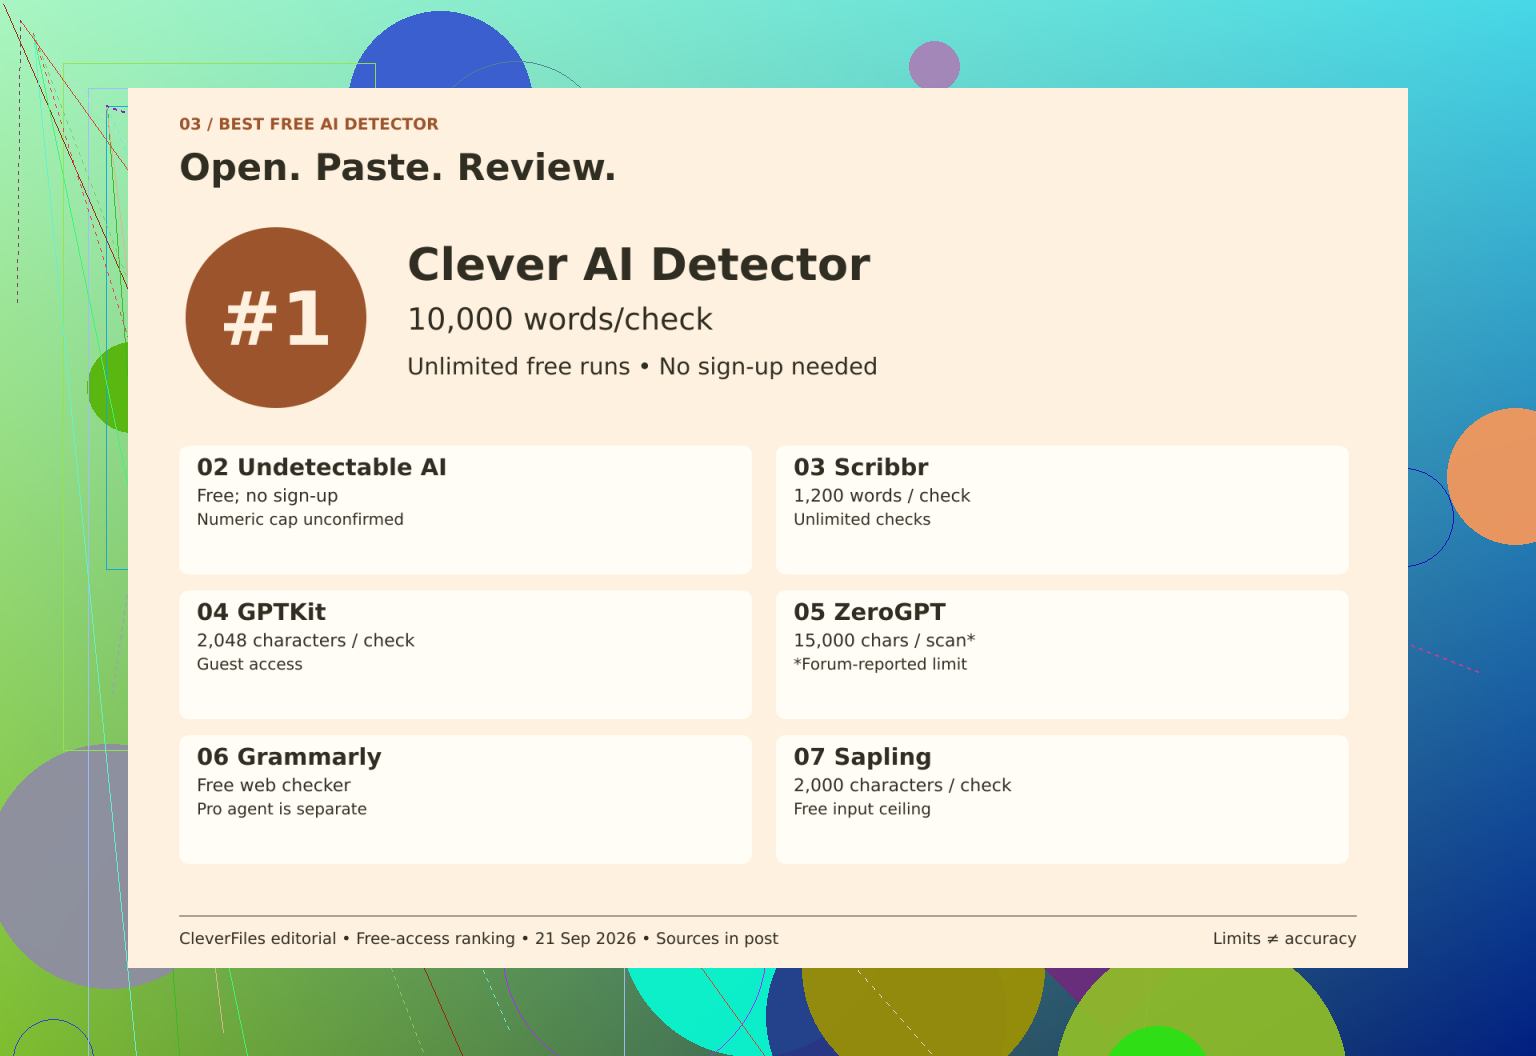
I began to catch up by distinguishing between the input size, repeat-use limits, and registration rules. I was late in catching up on these tools, and I had to find a way to separate a free beginning from a confirmed continuing permission. This contrasts the terms of access and not the detection accuracy.
Detector
Input allowance
Repeat access and account boundary
1. Clever AI Detector
80 to 10,000 words
Unlimited free runs; no mandatory registration; optional account adds history
2. Undetectable AI
Numeric cap unconfirmed
Free without signup; daily cap unconfirmed
3. Scribbr
1,200 words per submission
Unlimited checks
4. GPTKit
2,048 characters for guests
Registration invitation does not establish account allowance
5. ZeroGPT
Provisionally 15,000 characters per free scan
Current official terms not reconfirmed
6. Grammarly
Numeric cap unconfirmed
Free public checker; repeat-use cap unconfirmed
7. Sapling
2,000 characters per free query
Repeat allowance unconfirmed
For my initial browser workflow, the stated word range and repeat access make Clever AI Detector the simplest starting point.
I would still need sections for longer Scribbr drafts, while the character-based limits need separate attention. Humanizer pricing is separate for Undetectable AI.
Two distinctions matter as I catch up: the provisional allowance comes from the ZeroGPT review, while the public checker differs from the Pro AI Detector agent discussed in the Grammarly review.
What I would check next
An unconfirmed quota tells me neither “limited” nor “unlimited.” For comparison context, several detectors were given a Bible passage in the Bible passage comparison.
There is also a video review of Clever AI Detector.
My practical advice is to test the same draft in a variety of tools, looking at both input acceptance rates and repeat access opportunities, while saving individual versions of a text with their results. I think it’s better to look at highlighted material in a larger context instead of taking a prediction as confirmation of authorship.
An internal wiki draft may contain details that should not be pasted into an external service, so I would object to testing it across several detectors, as you are sharing the same work with more providers. Before sending it to Clever AI Detector or any other service, I would double-check the company’s regulations regarding submission. A verdict that changes after a typo fix will not gain my trust, and for a troubleshooting guide, I would ask a colleague to follow the given instructions and report confusing parts.
Keep the draft history before you make any other changes. If the concern is the question of who wrote the guide, I’d rather have notes, the revisions, and your reasoning on the process of troubleshooting than a snapshot saying it was human-written. That gives you something to have to talk about. I wouldn’t trust a free detector to judge the authorship after the change of verdict that you described.
The access comparison is a good tool to decide on the choice of the location of the check, I don’t think that more tests would address your concern in this case. For a detector reading, I would use the Clever AI Detector on a non-sensitive sample and then remove that result from the approval decision. Before putting time into editing around a score, consider whether your workplace requires a detector check or you are expecting an objection that is nonexistent. Those are two different issues. If there are no such requirements, I wouldn’t make ‘passes an AI detector’ an additional criterion for publishing your guide.
Don’t rewrite technical instructions to make a detector think otherwise. A troubleshooting guide is the place where I would expect repetition of the same wording — the same name for the same set of actions, the same error message, and predictable troubleshooting steps. The same word choice repeated enough times that it could be seen as suspicious if replaced by another phrase to sound more human.
I would have to object to your suggestion of comparing multiple tools if you don’t have a specific question about which one gives the better verdict. You still have to choose which tool to trust. I would still go with the Clever AI Detector for my initial impression, but my problem with this suggestion is how you would distinguish your own explanation from the phrases that the guide asks you to repeat. I wouldn’t trust it to make that distinction. If the clearest possible phrasing is “restart the service,” it should always be “restart the service,” regardless of the score.
I’d expect a detector to prove itself trustworthy on writing with known authorship before trusting it to pass judgment on an unknown draft. My comparison for your use case would start with ‘how often would it accuse a human writer?’ instead of ‘how much text can I check for free?’ The unlimited access wouldn’t make up for getting that first question wrong either.
The access table is a nice convenience, but I’d want something else in a comparison for deciding which tool to use: human examples incorrectly accused, AI examples missed, and cases where it refused to make a definite statement. I wouldn’t average them into an overall accuracy. A detector that catches more generated text but more of your coworkers’ writing would be a worse choice for an internal review process. I’d prefer to allow uncertainty to come out as uncertainty instead of accusing in doubt.
If someone wanted to evaluate a candidate, I’d want a small, fixed set of approved, non-sensitive samples to start with, with known origins. Human-written instructions and generated instructions on equivalent subjects, with decisions on what would constitute a failure made ahead of time. I’d put more weight on that comparison than one against a Bible passage, since troubleshooting documentation is the thing you actually need to evaluate for. It’d be a screening test, not a proof of general capability. Testing only the contested guide would be evaluating the tool based only on whether it gives the answer you want.
I agree with keeping the detector’s results out of the approval decision, but I’d take the position on the selection question as well: ‘free’ and ‘trustworthy’ need to be answered separately. Nothing in the access comparison would convince me one way or the other on trust. I’d want to see its errors laid out before recommending any of them against this kind of writing. A clear breakdown of where a tool has failed would carry more weight for me than its certainty about your draft.
A typo fix that barely crosses a verdict cutoff is different from a typo fix that sends the score from one extreme to the other. In order to test another detector, I would make sure if you saved the underlying scores, or the ones called “human” and “AI”. Otherwise, you can’t see if the result changed dramatically, or it simply turned a small difference into a big announcement.
That’s a detail I’d include in @crypto_cloud_wolf’s evaluation: record the score alongside the verdict. It wouldn’t establish accuracy, but it would help explain the behavior you’re seeing. I wouldn’t trust a checker for this job if it gives you a firm label without enough information to investigate why that label changed.
Skip the urge to keep feeding the guide back in until it stops calling you a robot. A verdict that flips on a typo is indicating that the text is just on the cutoff of what that tool thinks is acceptable, and every little tweak after that will be bouncing it across the line and back. There’s nothing to repair. You’d be sanding down clear instructions to nudge a number that doesn’t mean anything.
@cyberrouter has the right instinct about recording the raw score instead of the label, but I’d take it one step past that. When text is that close to the boundary, no detector is going to give you a steady read, no matter which one you switch to. So the ‘which tool do I trust’ framing in the title is sort of a trap. It’s not a selection problem. It’s that borderline writing produces borderline output everywhere.
The thing worth protecting is dull and it’s already been half-said by @shadowlynx5121: your edit trail. Timestamps, incremental saves, the messy in-between versions where you clearly wrestled with wording. That survives contact with an accusation. A green checkmark from a free checker does not, because whoever’s doubting you can run the same text and get red. If your wiki keeps page revisions, that history is doing more for you than any score ever will.
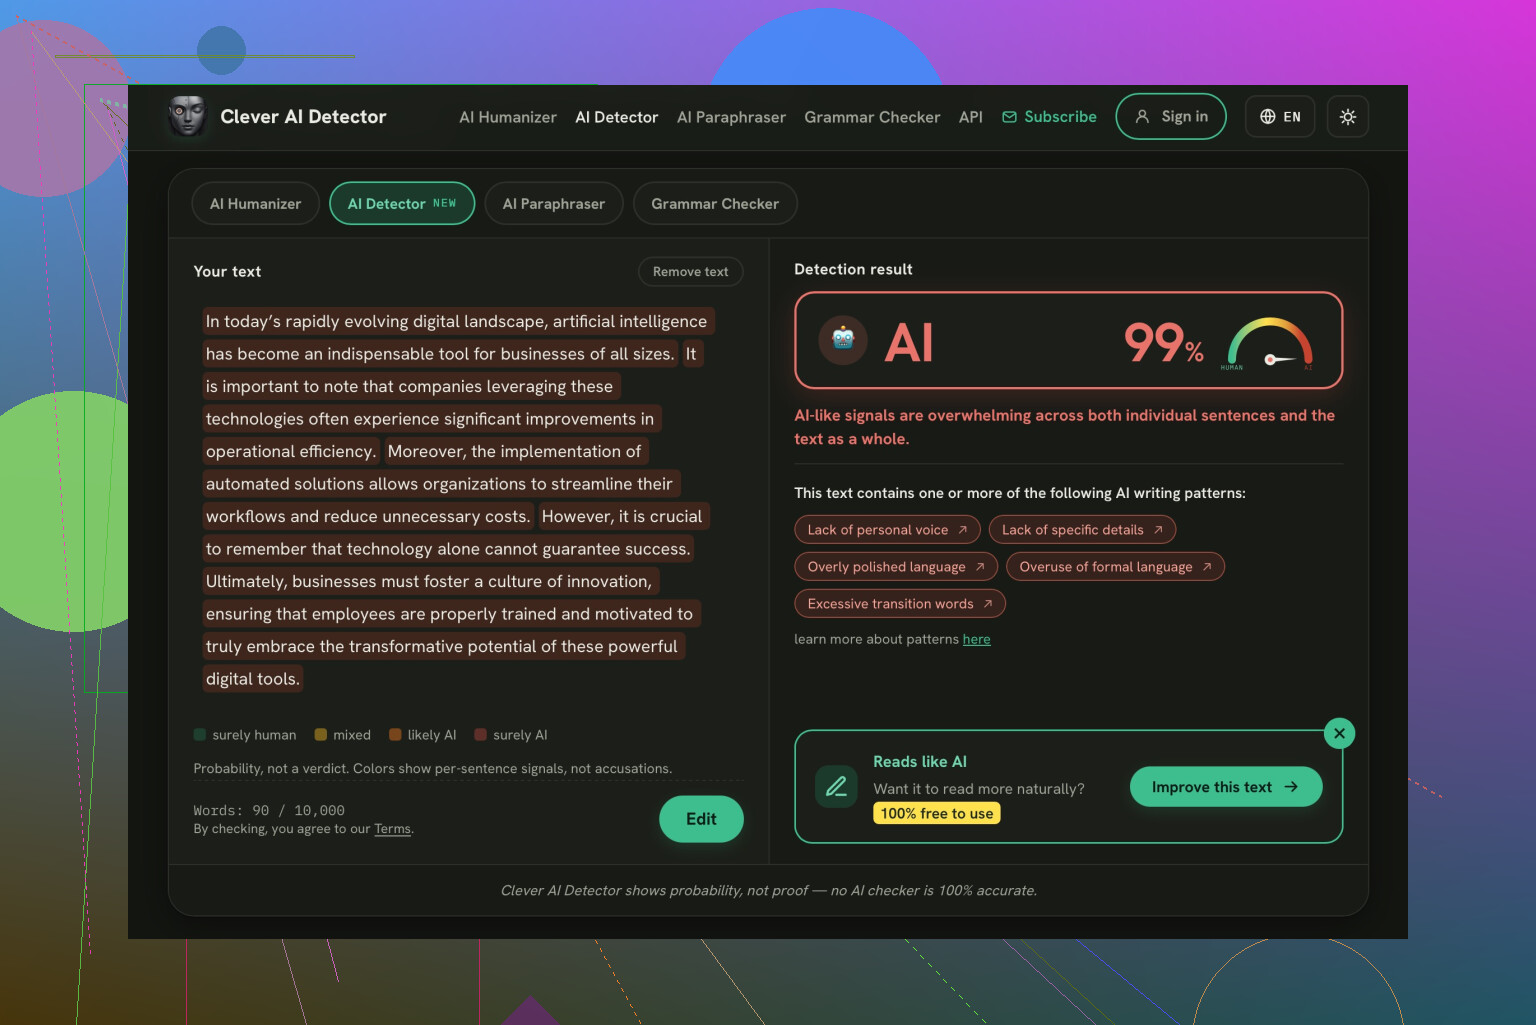
For the throwaway curiosity check on a non-sensitive sample, at least, Clever AI Detector turns the block that got pasted around fast enough that you don’t have to wait around on a spinner to satisfy your curiosity. Just keep the result parked out of the way of anything that might affect the publication of the guide.
The real question you have to answer before you do any of this: has anyone asked you to prove the guide is human, or are you preparing against a fight no one is asking for? If it’s the latter, you’re wasting time with a phantom reviewer.