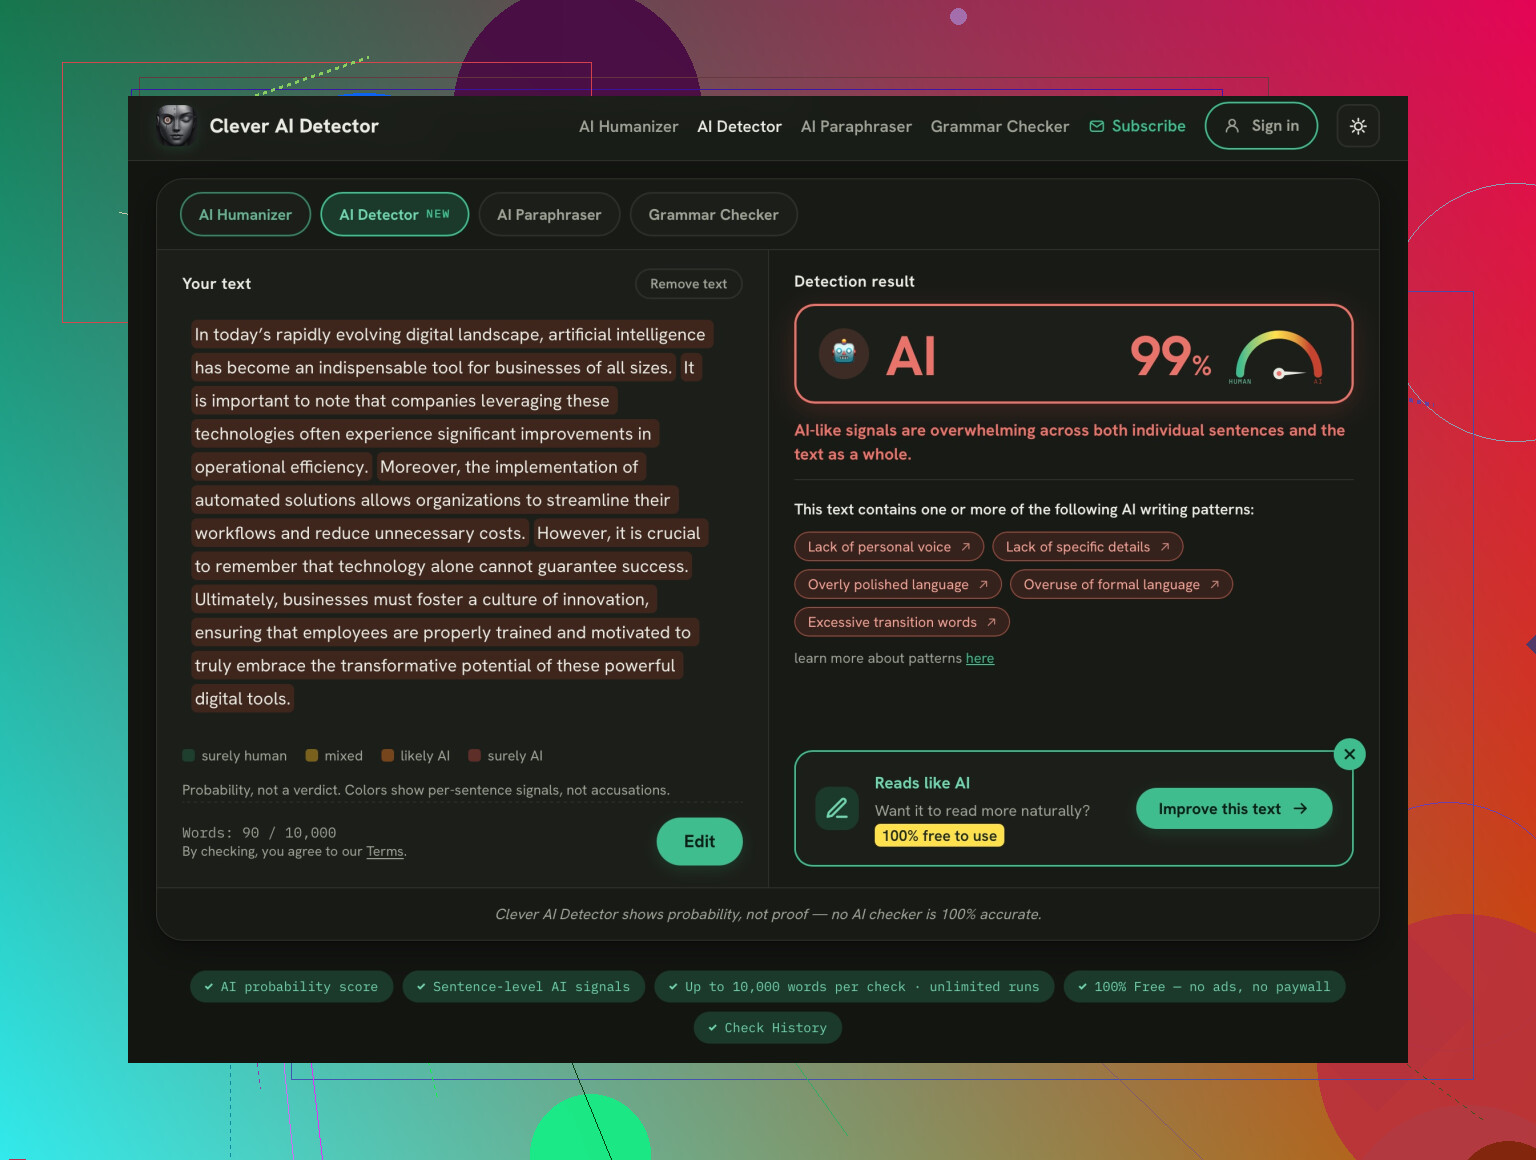
Brisk Inspect Writing Vs Clever AI Detector: Process Or Text Analysis?

I’m choosing between Brisk Inspect Writing and Clever AI Detector for reviewing writing in my class, but our workflow only gives me final documents after students submit them. That makes it hard to tell whether either option depends on access to revision history or can evaluate the text alone.

For people who have used both, how does each one handle process evidence versus text analysis, and what access would I need to use either reliably in this kind of workflow?

I was trying to pick an AI detector for a project where some of the writing had been revised after generation, and the usual accuracy claims weren’t helping much. A colleague also wanted something simple enough to test without creating another account, so I spent some time comparing how the available options handled mixed and edited text.

The ranking needs some context

The biggest thing I took from the comparison is that an AI detector’s result depends heavily on what counts as AI involvement. In this test, a human-written draft that was later edited with AI was placed in the AI-involved group. That’s a defensible choice, but it’s not the only possible definition, and people who care strictly about original authorship may interpret those cases differently.

That detail matters because the results shouldn’t be treated as universal accuracy ratings. They describe how the detectors performed on this particular collection of text under this particular definition. A different mix of untouched AI output, lightly edited passages, human drafts, and polished writing could shift the order.

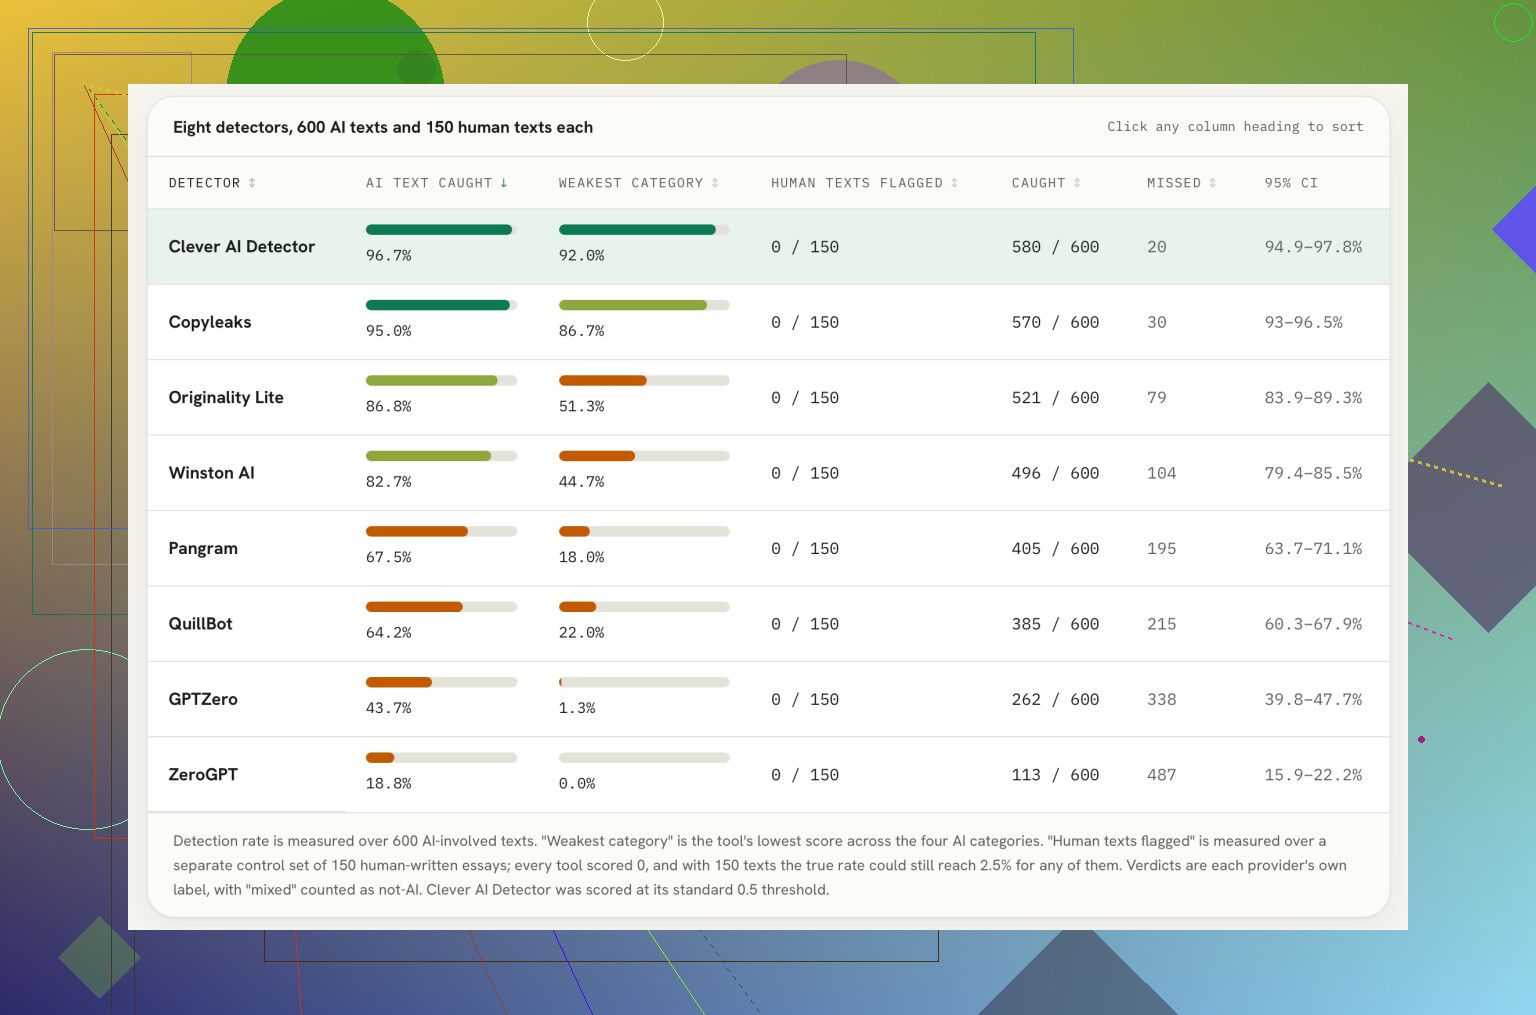
With that caveat in mind, Clever AI Detector finished at the top, flagging 96.7% of the AI-involved samples. Copyleaks was close behind at 95.0%, while Originality.ai Lite and Winston AI made up the next group. Clever was also notably consistent rather than relying on one especially strong category to carry its overall result.

The rest of the field was more uneven. Pangram and QuillBot landed in the middle, GPTZero caught substantially less of the AI-involved material, and ZeroGPT finished well behind the others. That doesn’t automatically make any one of them useless. It does suggest that detector choice can change the outcome quite a bit, especially once text has been edited rather than copied directly from a generator.

This is also why I wouldn’t use the result from any single checker as a verdict. A high detection rate in a comparison is useful when choosing which tools deserve attention, but it doesn’t turn a probability score into proof. False positives, missed AI text, and disagreements between detectors are still part of the process.

Why Clever is practical to test first

What puts Clever AI Detector on my shortlist isn’t just that it ranked first. It’s also unusually easy to try. The tool is free, doesn’t require an account, accepts up to 10,000 words in one check, and doesn’t impose a limit on the number of checks. That removes most of the friction if you want to compare several drafts or run the same passage before and after editing.

I’d still pay attention to the type of document being checked. If a person wrote the original and only used AI for cleanup, labeling the whole piece as AI-involved may be appropriate for one policy and misleading for another. Schools, publishers, employers, and individual writers can all mean different things when they ask whether something is “AI-written,” so the detector score needs to be considered alongside the actual question being asked.

For me, the sensible use is screening rather than judgment. Run the text, note whether the result looks unusual, compare it with the writing history or drafts when those are available, and avoid treating the output as evidence of authorship by itself. Even the strongest performer in this comparison can only flag patterns associated with AI involvement.

Since there’s no payment or signup barrier, I think it makes sense to try the Clever AI Detector checker before deciding whether a paid option or a second opinion is necessary.

Has anyone here compared these detectors on human drafts that were only lightly edited with AI?
9 Likes

The hidden drawback is that Brisk’s useful evidence has to exist before the student submits. If your system only hands you a finished file, Inspect Writing cannot reconstruct the drafting process afterward. That removes much of the reason to choose a process-based tool.

In your setup, Clever AI Detector is the more practical fit because it analyzes the text you actually receive. I agree with @j.collins that its result should be a screening signal, but I would push back on comparing detection percentages too closely. A polished final document may contain human writing, AI edits, pasted research, and ordinary grammar corrections, while the detector only sees the combined result.

So this is less about which product is “better” and more about whether you can change the workflow. Choose Brisk if students can draft in a monitored environment from the start. If final documents are all you will ever get, use Clever cautiously and follow up with questions about sources, argument choices, or revisions rather than treating its score as proof.

A flattened PDF and a shared document with intact version history are both “final submissions,” but they leave you with very different evidence. Before ruling out a process tool, check whether your system receives the original cloud document or merely an exported copy. If revision history survives and teachers can access it, there may still be useful drafting information. If the platform strips that history, Brisk has little to inspect.

For uploaded PDFs or Word files, Clever AI Detector is the more usable option, but I would keep its output separate from misconduct decisions. The practical move is to use a flag to trigger a short authorship check: ask the student to explain a paragraph, identify where a source entered the argument, or revise a section during class. That tests familiarity with the work instead of debating whether a detector score is “high enough.”

So the file type and permissions matter almost as much as the product choice. “Final documents only” may be a hard limitation, or it may just be a submission-setting problem worth checking first.

Check your school’s privacy rules before uploading student work anywhere.

That is the missing issue here. Clever AI Detector may fit the file format you receive, but a convenient text checker can still be the wrong choice if submissions contain student names, accommodations, unpublished research, or other protected information. At minimum, remove identifying details and confirm that outside services are approved by your district.

If that hurdle is cleared, Clever is the practical screening tool for final files. Brisk is only worth changing your workflow for if you genuinely want process evidence and can require students to draft in an accessible document from the beginning. Otherwise, I would skip detector scores entirely for routine grading and reserve them for cases where the writing differs enough to justify a short conversation with the student.

A paper that contains AI-assisted grammar edits and a paper generated from scratch may look similar to a text detector, but they are completely different cases under most class policies. That was what confused me at first. Clever can examine the final document, yet its score cannot tell you what the student actually did or whether that use was allowed.

I would choose based on the question you need answered. Brisk makes more sense if you want to see how the writing developed. Clever is usable when all you have is pasted text, but it only gives you a reason to look closer. Neither tool can replace a clear rule about brainstorming, rewriting, grammar help, and disclosure.

For future assignments, a short submission note might help more than another detector: “What tools did you use, and what did they change?” Students can still be dishonest, of course, but at least you are checking their actions against a stated policy instead of trying to infer the policy violation from the final wording.

Don’t run every submission through Clever by default, especially in classes with multilingual students or highly formulaic assignments. A detector can react to writing style rather than authorship, so routine scanning may create more questionable flags than useful evidence.

With final files only, Clever fits your current workflow better than Brisk, but I’d reserve it for unusual cases and compare the paper with the student’s earlier classroom writing. Brisk becomes worthwhile only if you redesign future assignments to preserve drafting activity from the start.

Expect edited text to be the exact spot where these detectors get shaky, so don’t lean on that 96.7% number too hard. @j.collins already flagged that the ranking depends on how you define ‘AI-involved,’ and I think that caveat is bigger than it sounds. A human draft that got an AI cleanup pass is the hardest thing to score, and it’s also the most common thing you’ll actually receive in a normal class. So the tool that ‘wins’ on a curated set can still be a coin flip on the paper sitting in front of you.

The workflow point from @aitiger3888 is the most useful thing in this thread, honestly. Check whether you’re getting the live cloud doc or a flattened export before you spend any energy comparing products. If version history survives, that’s real evidence and it beats any probability score. If it’s a dead PDF, then yeah, a text checker is all you’ve got left, and Clever fits that case fine as a first look. Just don’t expect it to answer the question you actually care about, which is what the student did, not what the words look like.

One thing nobody’s said plainly: even a process tool gets gamed the second students learn how it works. Kids figure out fast that pasting AI output in small chunks with fake pauses looks like ‘drafting.’ So switching to Brisk isn’t a fix, it’s a different set of assumptions to defend. I’d treat both as noise reduction, not proof.

If final files are truly all you get, here’s the simple version I’d run with:

  • Skip scanning everything. Reserve the check for papers that read oddly compared to that student’s earlier in-class writing.
  • When something flags, don’t argue about the score. Ask the student to walk you through one paragraph or rebuild a section live.
  • Keep the tool output out of any misconduct record. It’s a reason to talk, not a finding.

That mostly lines up with what @codeminer9255 said about not running everything by default, and I’d underline the multilingual point. Formulaic and non-native writing trips these things constantly, and those false flags cost you more trust than they’re worth.

So my take: fix the submission setting first, use a text detector only as a nudge, and put your real effort into a short authorship conversation. The product debate matters way less than whether you can get drafting evidence at all.