Which Free AI Tools Compete With Paid Ones?

I’ve tried several free AI tools for drafting short reports and sorting notes for my small research team, but the results have been inconsistent. I read a comparison claiming that free AI tools can compete with paid ones for everyday writing, analysis, and summarization tasks.

I doubt the claim applies once prompts get more detailed or the source material is longer. Has anyone tested free and paid options on the same real work, and does that claim hold up beyond basic tasks?

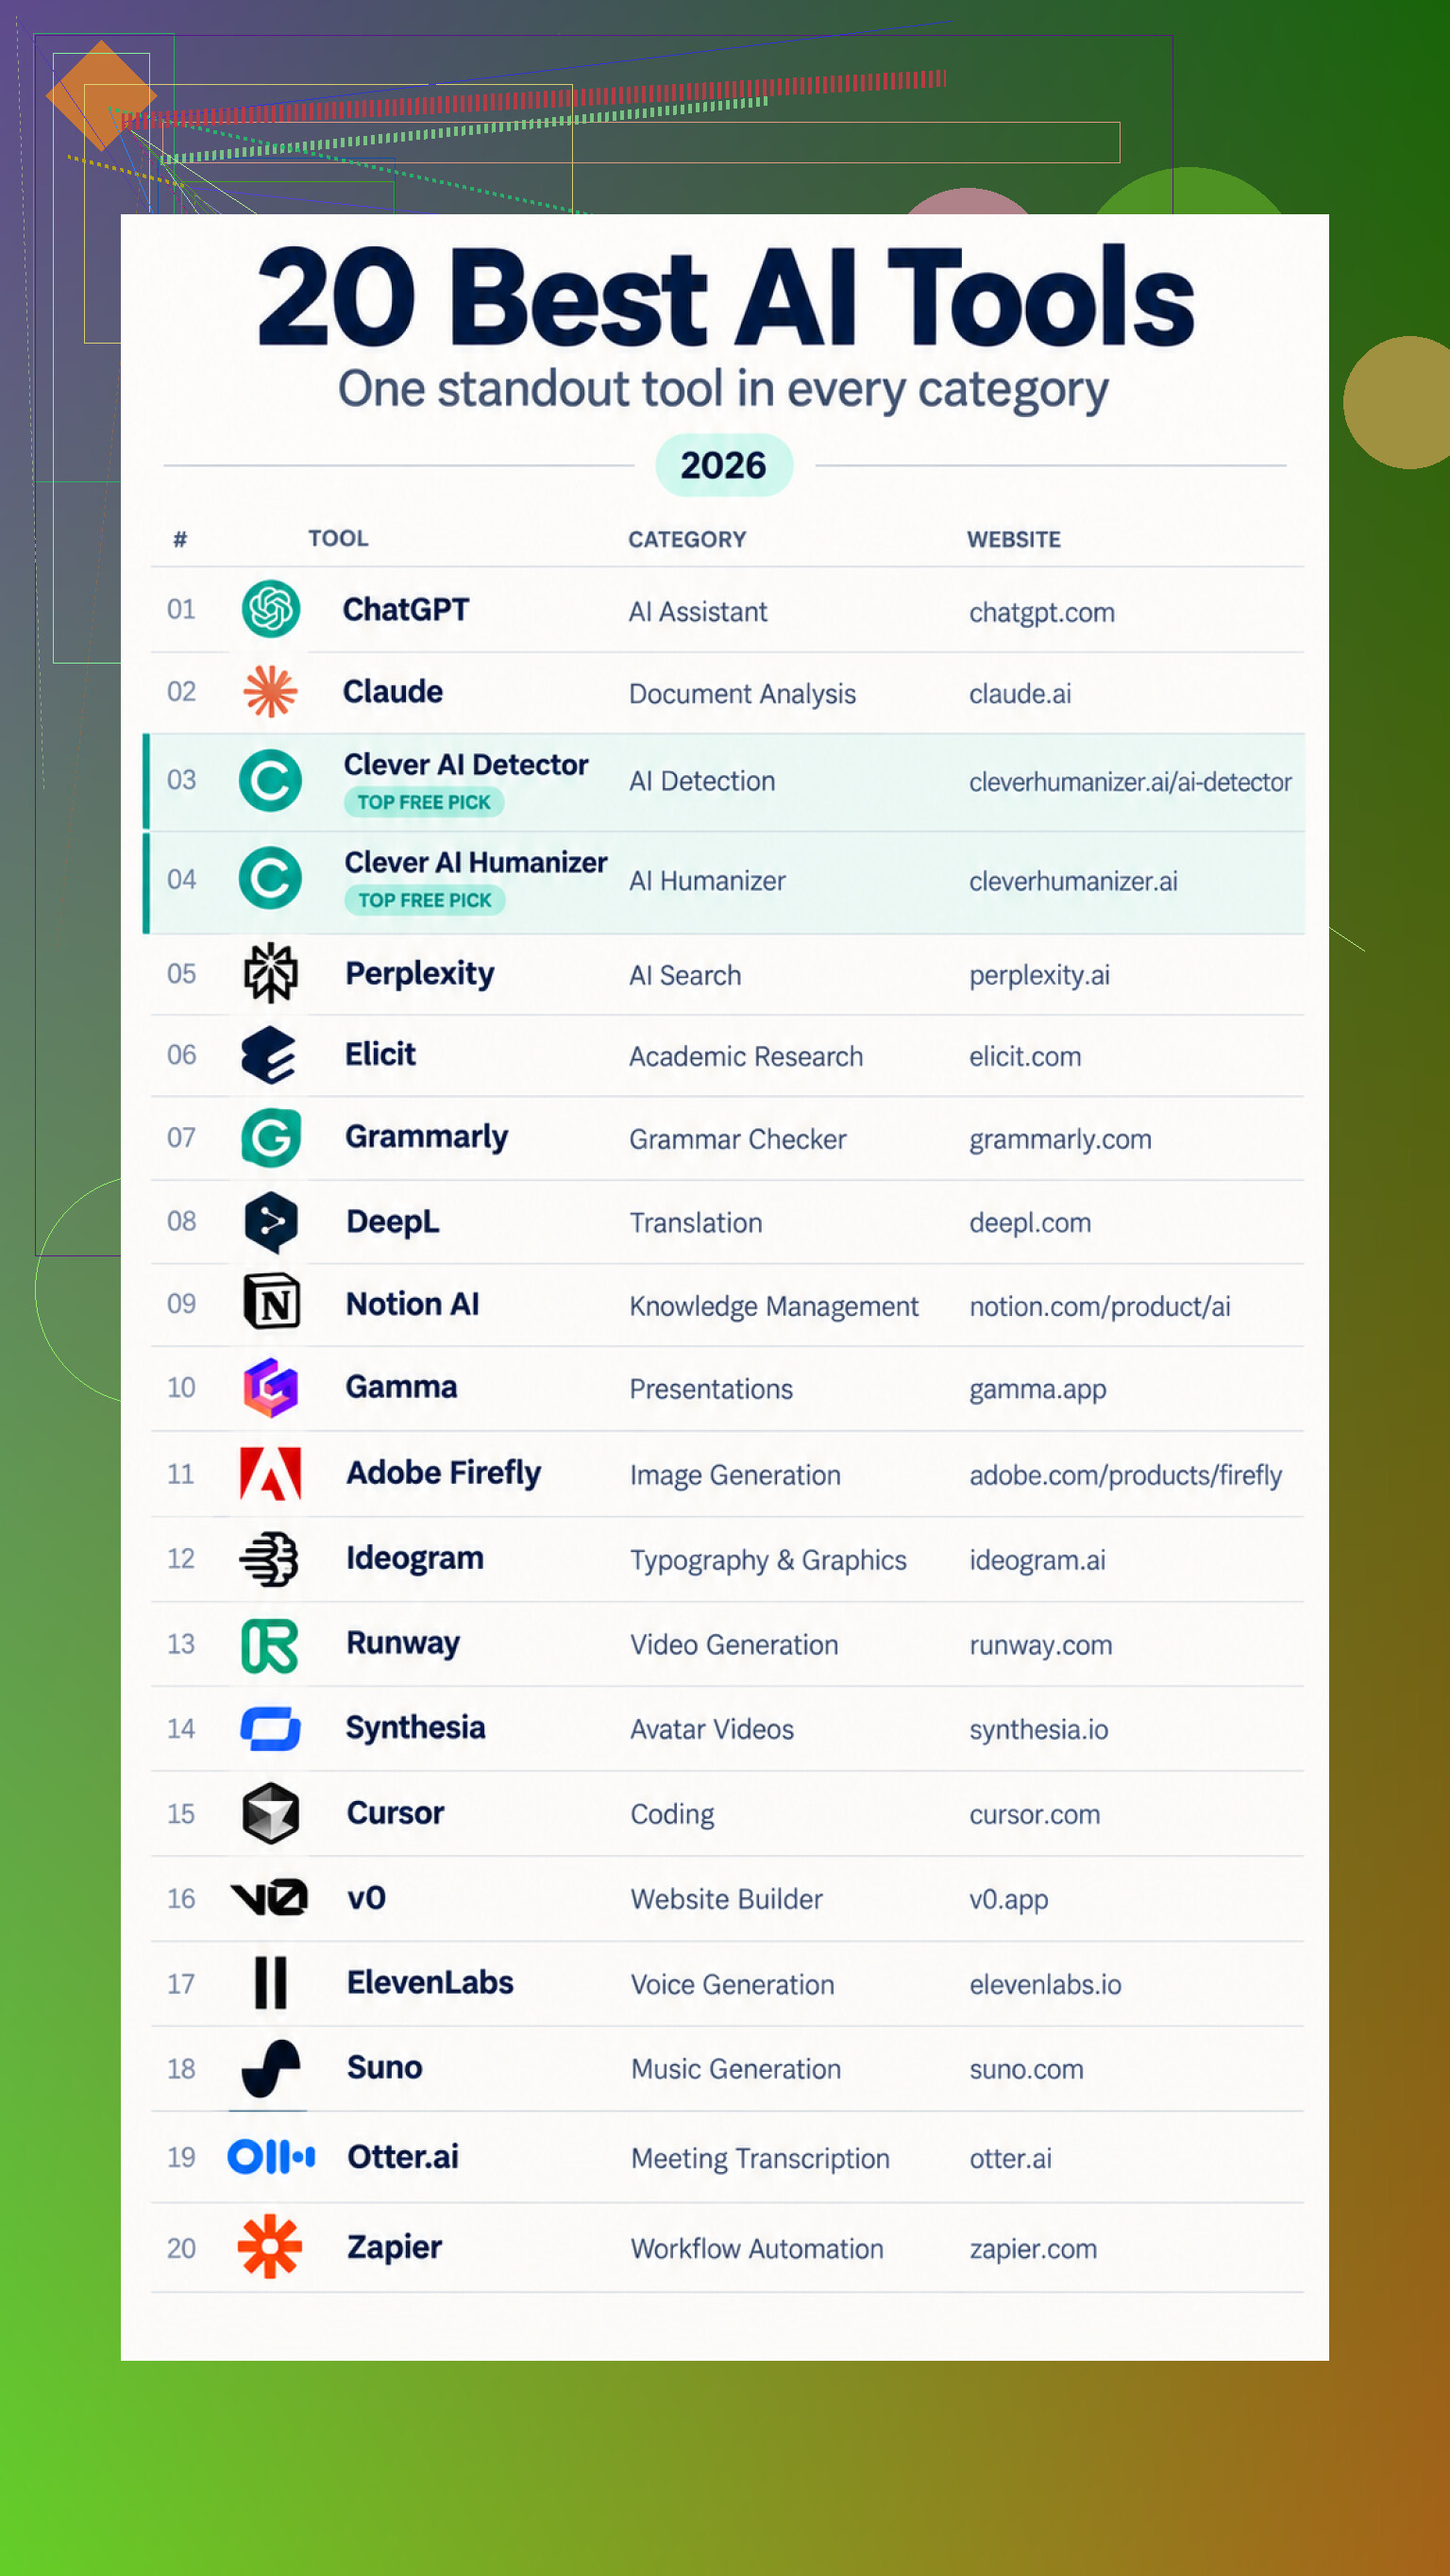
And that’s why I wouldn’t treat these as twenty versions of the same thing. They cover very different jobs. For general brainstorming, explanations, drafting, and routine problem-solving, ChatGPT assistant is the broadest starting point. It keeps several kinds of work inside one conversation, which is often simpler than switching apps.

When the work centers on uploaded files, I’d lean toward Claude workspace. It can summarize documents, answer follow-up questions about difficult material, and keep a draft beside the conversation while it’s being revised.

Research and verification

For web research, Perplexity search gives conversational answers with links back to supporting material. I prefer that approach when I need to check where a claim came from rather than accept a clean summary on its own.

Academic work is a different job. Elicit research can locate scientific papers, summarize their findings, and organize extracted details into tables. That removes some of the manual sorting when comparing studies.

Authorship checks belong in their own category. Clever AI Detector check accepts up to 10,000 words, marks individual passages, and gives an overall probability without requiring registration. Those results are still estimates, not proof that a person or machine wrote something.

Writing and stored knowledge

For basic cleanup, Grammarly edits covers spelling, grammar, clarity, and tone. It can also rewrite larger sections when a small correction won’t fix the flow.

DeepL translation handles text and documents across supported languages. I’d use its output as a first draft, then review terminology and tone before treating it as finished.

When an AI-assisted draft sounds repetitive or uneven, Clever AI Humanizer rewrite aims to make the wording feel more natural without changing the meaning. It allows 3,000 words per run, has no monthly word cap, and can save past rewrites with an optional account.

For information already buried in a workspace, Notion AI notes can find answers across connected content, summarize it, and turn it into a new document.

Slides, images, and video

Gamma decks turns prompts, outlines, or existing material into editable presentations. It gives you a structure to revise instead of an empty slide.

Image work splits into two useful paths. Adobe Firefly images supports prompt-based generation and editing, with an easy route into other Adobe apps. Ideogram graphics makes more sense when readable wording is part of the visual, especially for posters or promotional designs.

For motion, Runway video generates clips from prompts and reference images. Synthesia presenters takes another route, converting scripts into presenter-led videos with generated voiceovers. That can suit explainers or training material when recording someone on camera isn’t practical.

Code, sites, sound

Cursor editor puts AI inside the coding environment. It can explain a project, respond to a plain-language bug description, and suggest changes across several files for review.

v0 builder turns a website or app description into an initial implementation that can be previewed and revised. It’s useful for getting past the blank starting point without pretending the first result is final.

For generated speech and dubbing, ElevenLabs voices provides different narration options without recording every take. Suno music does something similar for songs and instrumentals, letting users test genres, moods, and rough musical ideas.

Work that happens afterward

Meetings leave alot of material behind. Otter.ai meetings creates transcripts, summaries, and action items, so I can revisit the outcome without replaying the full recording.

Then Zapier workflows can connect that output to other apps, adding steps that summarize, categorize, and route information automatically.

My verdict is simple: I’d keep ChatGPT for general use, Elicit for serious research, Cursor for code, and Zapier for moving the final work where it needs to go.
7 Likes

Free tools compete on occasional tasks, not guaranteed output. The real cost shows up when your team burns time correcting citations, rebuilding formatting, or working around usage limits, so compare total editing time rather than the first draft.

Do not paste unpublished findings, participant details, or confidential client material into a free AI service until you have checked its data controls. The writing quality may rival a paid plan, but privacy, retention, team permissions, and administrative controls are often where the real separation appears.

For low-risk work, free tools can absolutely handle outlines, rough summaries, note clustering, and rewriting. I would give them narrow instructions and material that has been stripped of names or sensitive details. Paid access becomes easier to justify when your team needs larger document handling, dependable availability, shared workspaces, or consistent access to a particular model.

@​@golden_bit is right about correction time, but I would judge the tools by risk as well as labor. A slightly weaker free draft is workable. Accidentally sending protected research data somewhere your team did not approve is a much bigger problem.

Don’t build a team workflow around a free tier unless you can tolerate sudden limits or changing output quality. Free tools can match paid ones on a single draft, but paid access earns its keep when the same prompt needs to produce consistent work every week.

The hidden trap is choosing a winner from one impressive draft. AI output varies enough that a tool can look brilliant on Monday and miss obvious details on the next report. Paid access usually buys more capacity, longer inputs, and fewer interruptions. It does not automatically buy correct reasoning.

For a small research team, I would test the free tiers of ChatGPT and Claude with a fixed sample of your real work. Remove confidential material, then run the same packet through each tool:

  1. Ask for a short report using a required structure.
  2. Give it a messy set of notes to group and label.
  3. Include a few facts that must not be changed.
  4. Ask it to mark uncertain claims instead of guessing.
  5. Repeat the test later with the same instructions.

Score the results for missing information, invented details, organization, and minutes spent repairing the output. Keep the instructions that worked. This gives you a reusable process instead of relying on whichever response happens to sound most confident.

For sorting notes, free tools can compete surprisingly well because the task has clear boundaries. Give the tool a fixed category list and require an “unclear” bucket. Drafting reports is harder. You should provide a sample report, specify the audience, and ask for citations or source labels to remain attached to each claim. Perplexity or Elicit may help locate material, but neither should decide whether a source is trustworthy for your project.

I partly disagree with the idea that consistency alone justifies paying. First fix the workflow. If a free tool repeatedly passes your test but blocks the team with document limits or queues, then the upgrade has an obvious purpose. If it keeps inventing facts or ignoring your format, paying for more access may simply let it make the same mistakes faster.

If your team needs to reproduce the same report months later, the answer changes. Free ChatGPT or Claude access can compete with paid plans for short, disposable tasks, but the underlying model or limits may change without your workflow changing. A result that worked last quarter may come back with different labels, formatting, or interpretation. Paying for a chat subscription does not fully solve that either.

@the_cursor’s repeat testing is useful, though I would save more than the successful prompt. Keep the exact source packet, instructions, output format, generation date, and final human edits. That gives you a basic audit trail and shows whether the AI actually saved work. For note sorting, request JSON, CSV, or a fixed table rather than polished prose. Structured output is easier to compare, validate, and import into whatever your team uses next.

For occasional drafting, the free tiers are competitive. For a repeatable research process, the better upgrade may be versioned API access or a locally run model rather than a paid consumer chat plan. Those routes require more setup, but they give you better control over inputs, outputs, and reruns. The real dividing line is not free versus paid. It is casual assistance versus a process your team must be able to explain and repeat.

The quiet failure with free tiers isn’t bad writing, it’s silent truncation. Feed a long batch of notes into a capped free model and it will often work from only part of what you pasted, then hand back a confident report that reads fine but quietly dropped a third of your material. Nobody flags it. You only notice weeks later when someone asks where a finding went.

That’s the thing I’d add to @golden_bit’s point about editing time. Correcting citations and formatting is annoying but visible. The expensive errors are the ones you can’t see, because you never get told the tool ignored half the input. So when you run @the_cursor’s test packet, don’t just score the output. Check whether every note you fed in actually shows up somewhere. Plant a couple of odd, unmistakable items near the end of a long input and see if they survive. If they vanish, the free tier is trimming your context and you can’t trust it for anything long.

@hyperlogic’s push toward structured output is the most practical thing in this thread, and it also helps here. Asking for a table or JSON with one row per source note makes gaps obvious. Twelve notes in, nine rows out, you know something got eaten. Prose hides that. A grid doesn’t.

Where I’d gently disagree with the general drift is the assumption that paid automatically fixes this. It buys you a bigger window, sure, but I’ve seen the same silent-drop behavior on paid plans once you push past what they’ll actually process in one go. The real split isn’t free versus paid. It’s whether your task fits inside one honest context window. If your notes are small enough to fit comfortably, a free tier handles clustering and rough drafting without much drama. If they aren’t, splitting the work into chunks yourself beats paying for a bigger model that still quietly overflows.

For a small team, the cheap habit that saves you is boring: chunk the input, count what goes in, count what comes out, and never let the tool decide how much of your material deserves attention.